New·5 min read
Small Vision Transformers: One-Step Images with MeanFlow
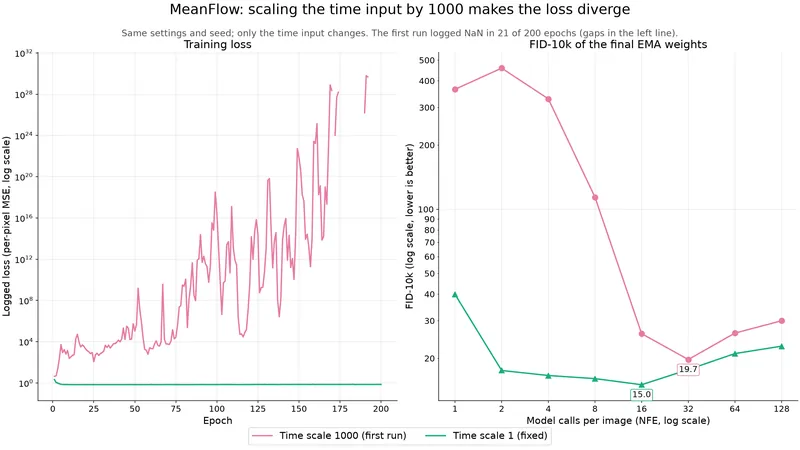
MeanFlow learns average velocities, so one model call makes an image: FID-10k 39.9 at NFE 1 and 17.5 at NFE 2. The first run diverged; here is why.
Lead AI Engineer · Writing since 2016
I write about reinforcement learning, transformers, multi-agent systems, and the tools I build along the way.
MeanFlow learns average velocities, so one model call makes an image: FID-10k 39.9 at NFE 1 and 17.5 at NFE 2. The first run diverged; here is why.
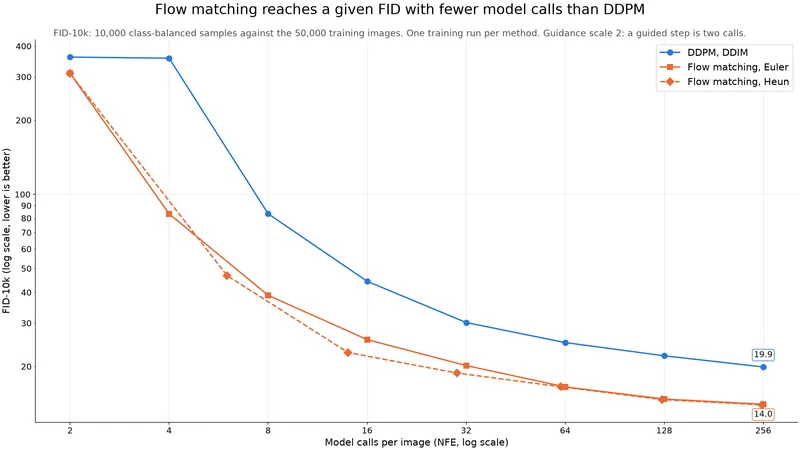
Same DiT, data and 200 epochs: flow matching gets FID-10k 20.2 with 32 model calls. DDPM needs 256 calls to reach 19.9. Euler and Heun samplers compared.
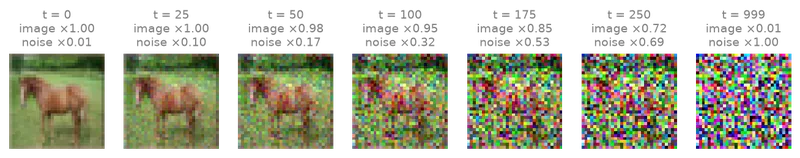
A 9.8 M parameter Diffusion Transformer learns to draw CIFAR-10 images in 86 minutes on one GPU. The loss is flat long before the samples look right.
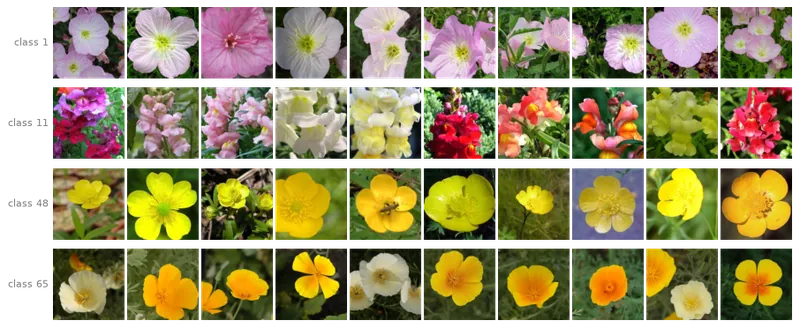
ViT-B/16 on Flowers-102 with 10 images per class: 39.0% from scratch, 98.4% with a linear probe and 99.2% with LoRA, plus a check for leaked test images.
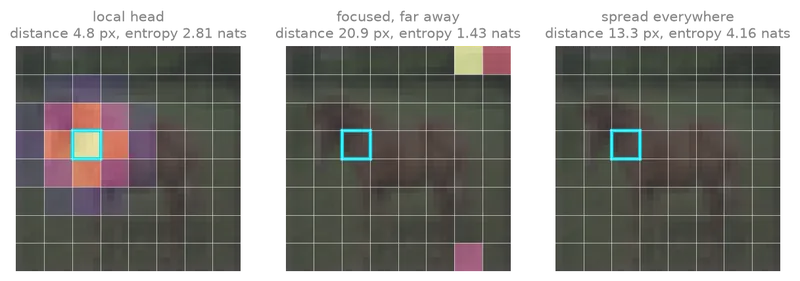
A small ViT trained on CIFAR-10 learns local attention in layer 1 and global attention in the last layers. The fixes that raise accuracy make it more local.
A small Vision Transformer starts at 57% on CIFAR-10 and reaches 92.9% after eight fixes. Each fix has a measured gain, and ResNet-18 still wins.
Sabattier is a free batch photo editor for Windows and macOS with auto enhance, masks, portrait retouching and background removal, all on your computer.
Read in order
Multi-part guides that build on each other, start to finish.
Subscribe to the RSS feed, or follow along on GitHub, LinkedIn and the RL Factory YouTube channel.